Kathy Garcia
πŸ† NeurIPS 2026 Β· Oral top 0.4% of submissions First author VSS 2026 Β· Poster

Behavioral Geometric Supervision Aligns Video Foundation Models with Human Social Perception

Johns Hopkins University

Today's best video models β€” including V-JEPA 2 β€” organize social scenes less like humans than a sentence embedding of a caption does. A compact behavioral signal fixes that: fine-tuning on human similarity geometry nearly triples alignment, beats language baselines, and transfers to abstract social interactions.

49,484
odd-one-out judgments from 245 people
250
naturalistic two-person video clips
2.8Γ—
RΒ² gain for V-JEPA 2.1 after BGS
81%
zero-shot accuracy on abstract PHASE interactions
Scroll for the story

00The story in eight steps

1 Β· The gap

Video models miss social structure

People watched 3-second clips of two-person interactions and judged which were alike. Across 14 pretrained vision encoders, none match that similarity structure as well as a sentence embedding of a one-line caption (MPNet) β€” even though participants never saw any text.

2 Β· The human signal

49,484 odd-one-out choices

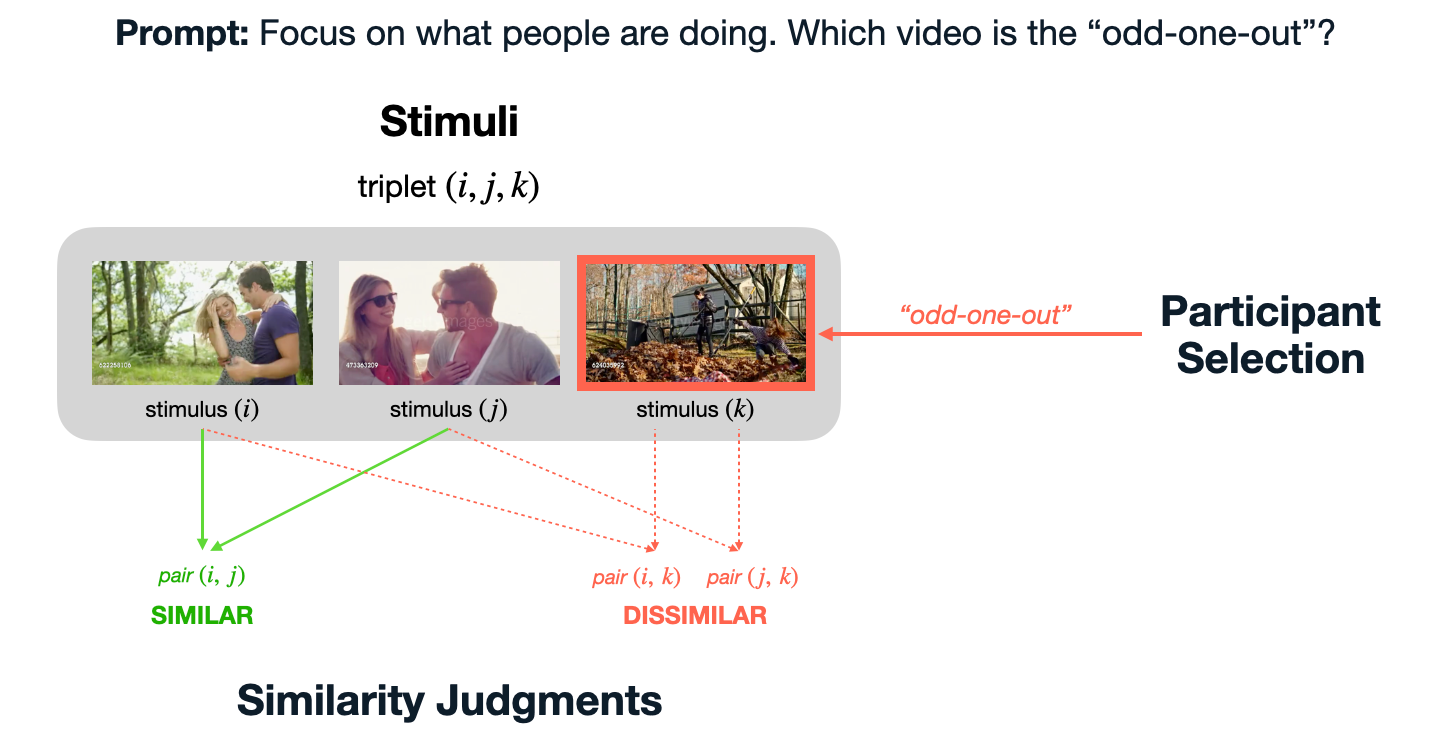
On each trial, 245 participants picked the odd-one-out of three videos, implicitly marking the other two as more similar. A greedy set-cover design guarantees every video pair appears in at least one triplet.

3 Β· Local geometry

Triplet loss: pull and push

At every step, the anchor clip (A) is pulled toward the clip humans judged similar (P) and pushed away from the odd-one-out (N). Only low-rank adapters (LoRA) and a small projector are updated.

4 Β· Global geometry

RSA loss: match the whole map

Six times per epoch, a differentiable RSA loss aligns the model's full pairwise-distance matrix on a 24-video subset with the human similarity matrix β€” shaping global structure that local constraints miss.

5 Β· Better together

The hybrid wins

On V-JEPA 2.1, the hybrid beats each loss alone and a budget-matched triplet model β€” so RSA adds different information, not just more constraints. A control that distills MPNet's caption knowledge instead falls far short.

6 Β· The result

Nearly triple the alignment

V-JEPA 2.1 ViT-B goes from RΒ² = 0.058 to 0.165 β€” 78% of the noise ceiling, past MPNet. Every backbone improves, and fine-tuned models capture variance that caption embeddings can't.

7 Β· Generalization

It transfers to moving shapes

On PHASE β€” interactions between animated triangles with no faces or bodies β€” the frozen BGS encoder reaches 81%, up from 55%, matching human agreement within sampling error. Action recognition is preserved.

8 Β· Mechanism

Attention moves to what matters

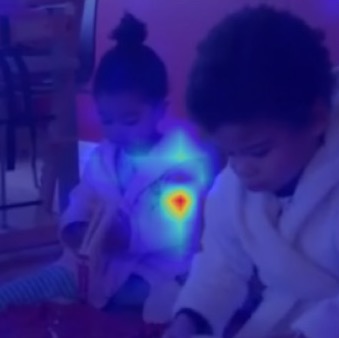
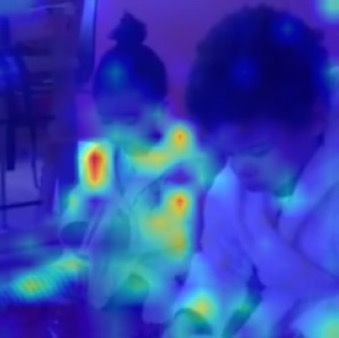
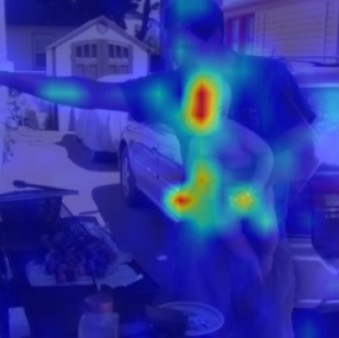
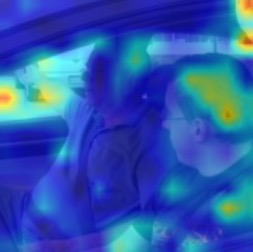
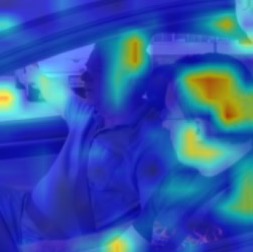
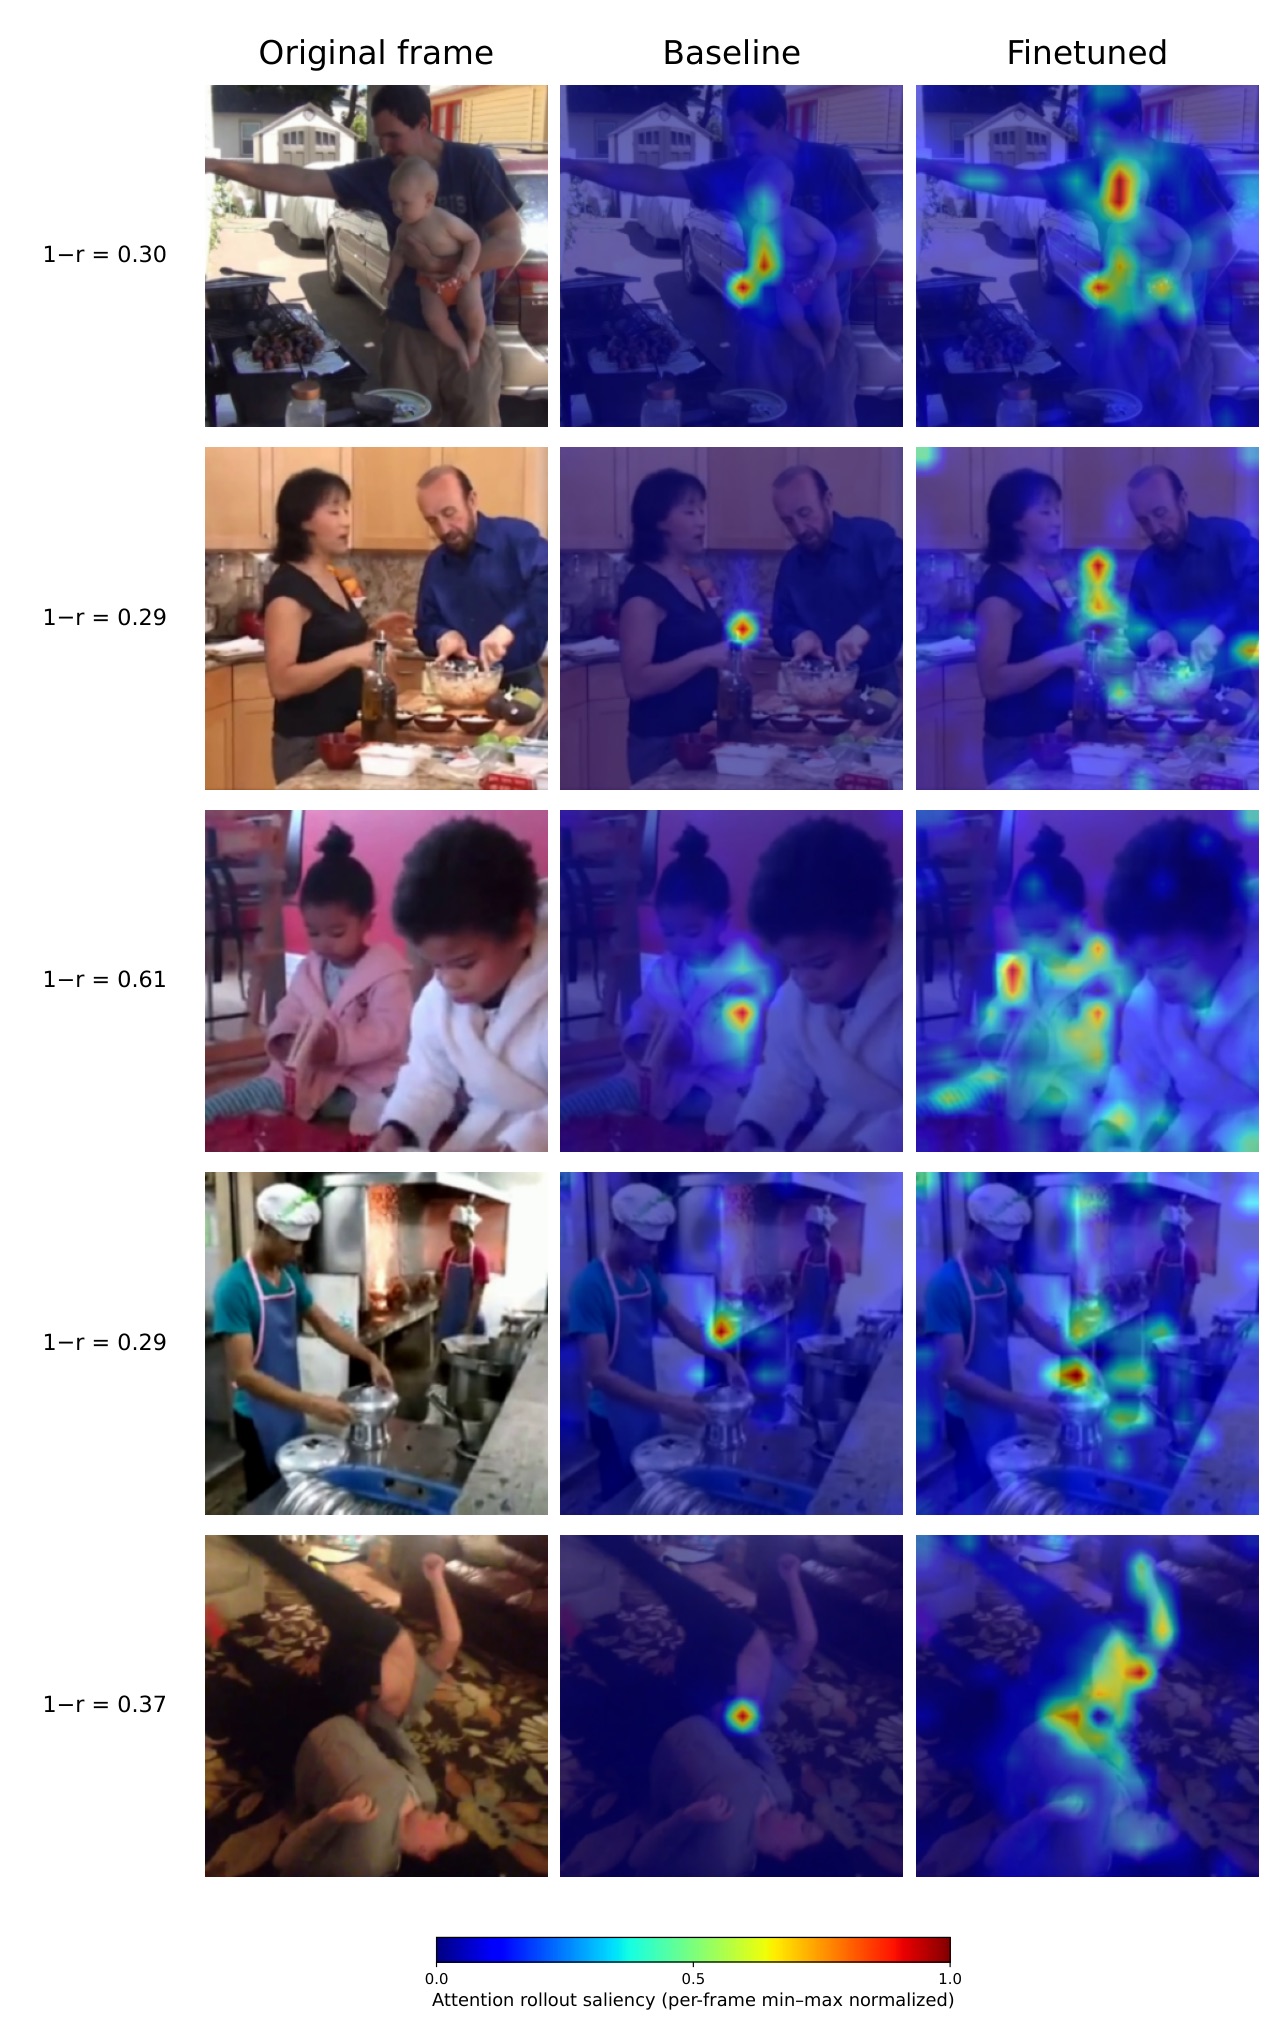
The pretrained model fixates on one region. After BGS, attention spreads across both agents, faces, gaze, and interacting hands β€” with no spatial supervision. Explore it below ↓
Alignment with human similarity (RΒ²)
Pretrained models vs. a caption embedding Β· dashed: noise ceiling 0.213
MPNet (captions)0.134
X3D-M (best video)0.124
V-JEPA 2 ViT-L0.087
V-JEPA 2.1 ViT-B0.058

Participants saw only video, yet text of a caption predicts their judgments best.

One trial = three pairwise judgments
β€œFocus on what the people are doing and choose the odd-one-out.”
Odd-one-out trial: the unchosen pair is labeled similar, the chosen clip dissimilar to both
Triplet loss Β· every optimizer step
Schematic of the embedding space
RSA loss Β· 6Γ— per epoch
Schematic: all pairwise distances nudged toward human similarity
V-JEPA 2.1 ViT-B Β· held-out RΒ²
β„’hybrid = Ξ±Β·β„’triplet + Ξ²Β·β„’RSA Β· dashed: noise ceiling
Hybrid (BGS)0.165
Triplet only0.158
MPNet (captions)0.134
RSA only0.131
Language-distilled0.123
V-JEPA 2.1 ViT-B, before and after BGS
Held-out RΒ² Β· dashed: noise ceiling 0.213
Pretrained0.058
MPNet (captions)0.134
+ BGS0.165
2.8Γ— more variance explained
PHASE: friendly / neutral / adversarial
3-way accuracy on 100 held-out videos Β· dashed: chance (33%)
Humans83%
V-JEPA 2.1 + BGS81%
V-JEPA 2.1 pretrained55%
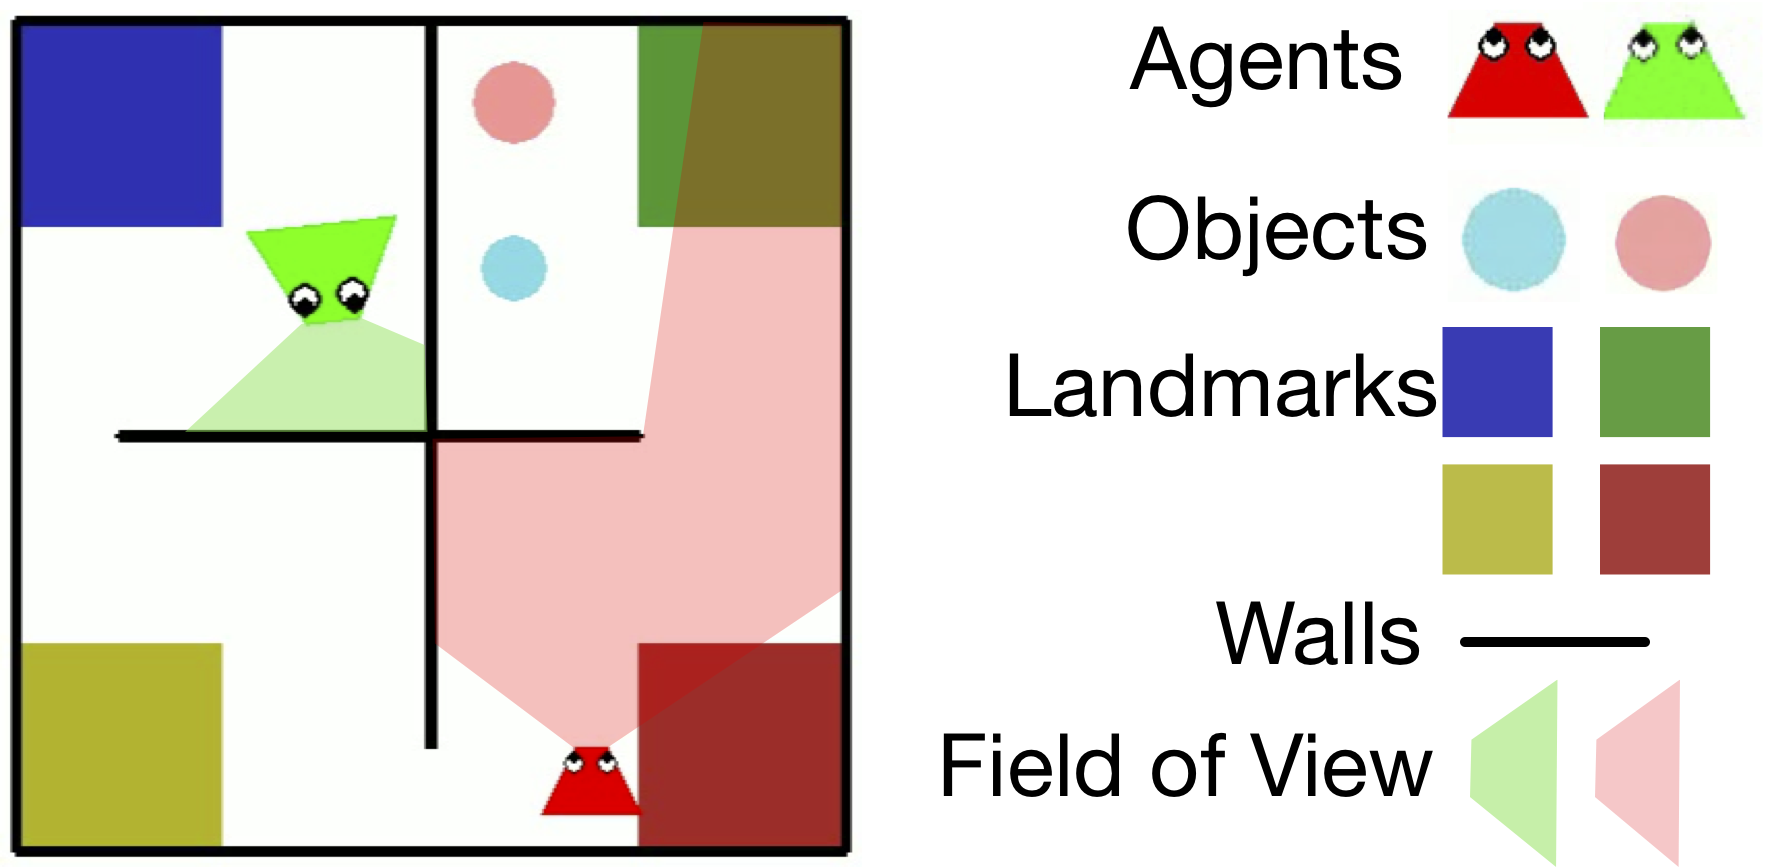
PHASE stimuli: two triangle agents in a 2D world
Attention rollout Β· V-JEPA 2.1
Crossfading pretrained ↔ BGS on the same frame
Pretrained attention BGS attention Pretrained+ BGS

01Try the task

Every judgment in the dataset came from a trial like this one. Each click implicitly says the other two clips are more similar, so one trial yields three pairwise constraints.

Which clip is the odd-one-out?
Focus on what the people are doing. There is no right answer; we want your intuition.

02Full leaderboard

Every model we tested, compared with the human similarity matrix using Spearman RSA. Toggle model families on and off, or switch to odd-one-out accuracy.

Alignment with human social similarity
Held-out test videos Β· higher is better

03Pick a backbone

BGS works across four families of pretraining β€” self-supervised prediction, supervised classification, masked reconstruction, and contrastive vision-language. Choose one to see how it changes:

Not just caption knowledge

Variance partitioning against MPNet shows two shifts after fine-tuning: structure that only the language model captured collapses into the shared component, and video-unique variance doubles (RΒ² 0.02 β†’ 0.04) β€” social-visual structure that even an idealized caption embedding cannot reach. Bootstrapping the 637 observed test pairs, V-JEPA 2.1 ViT-B rises from 0.043 [0.016, 0.080] to 0.160 [0.109, 0.216].

04Where the model looks

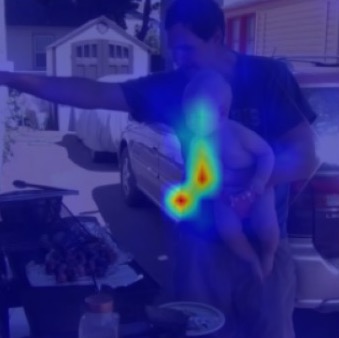
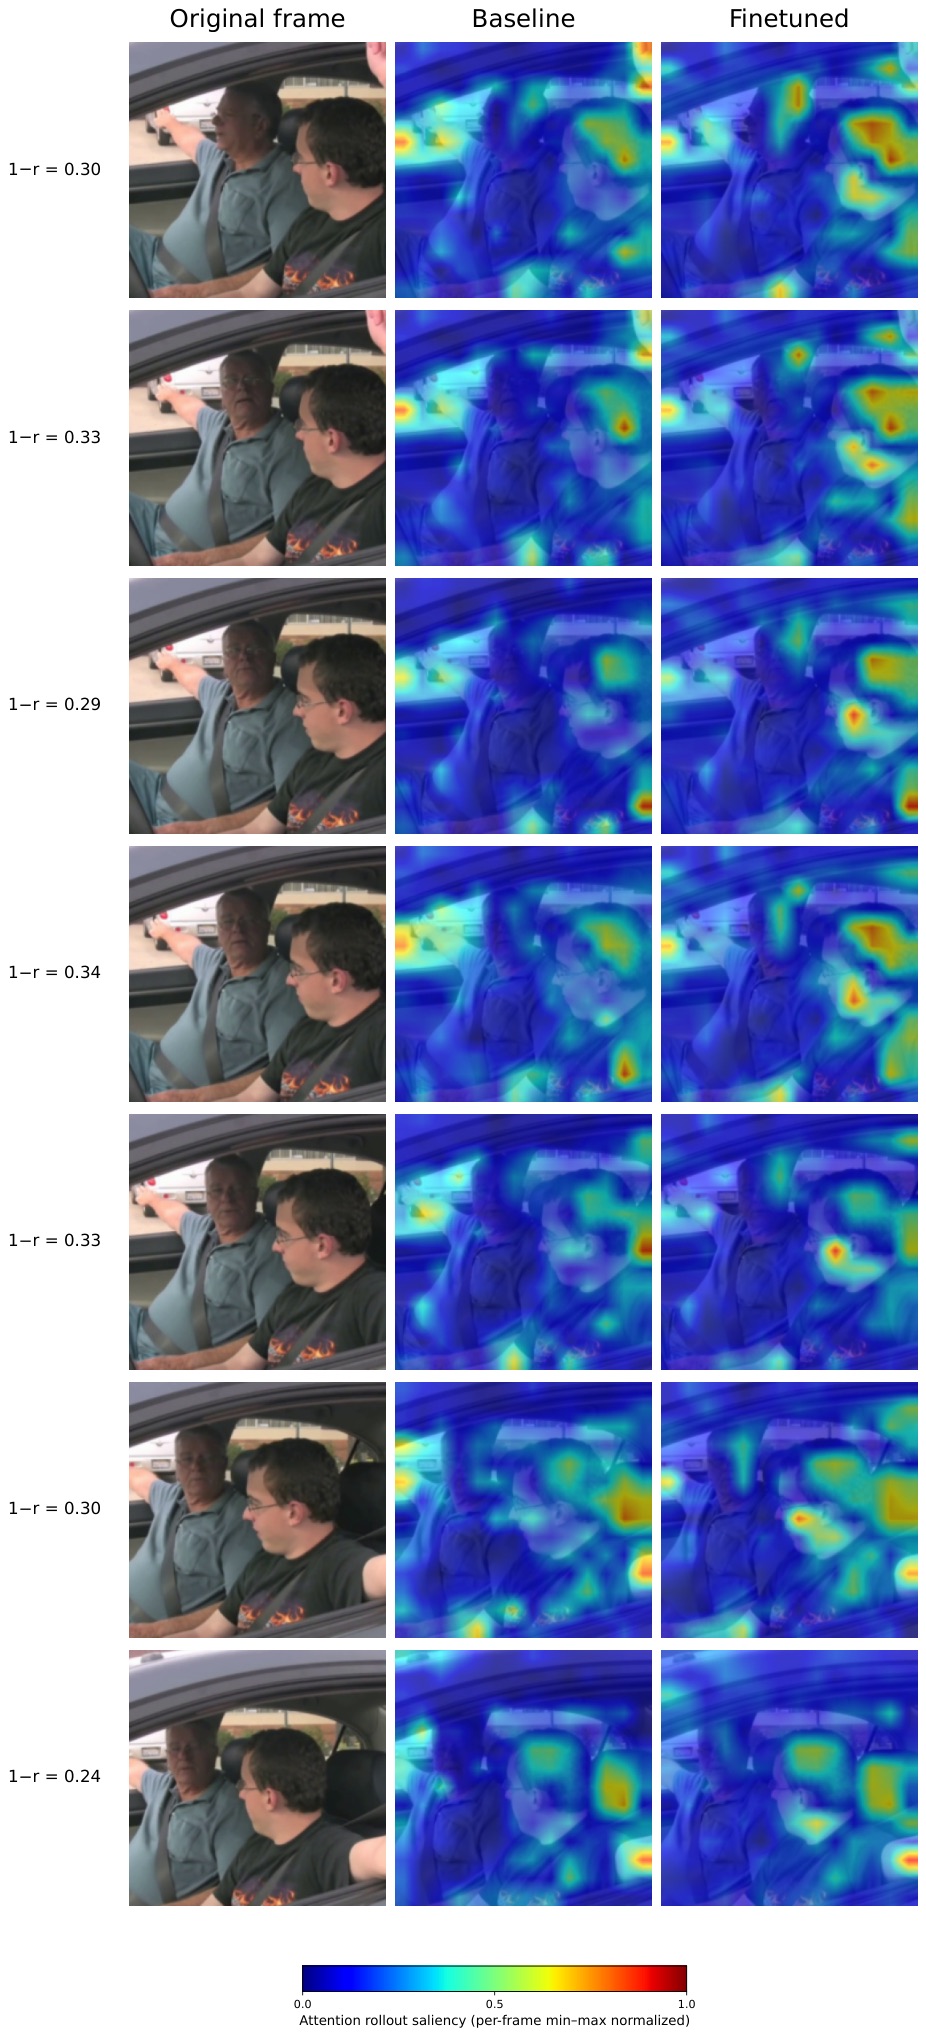
Drag across each frame to compare attention rollout before and after BGS. Across all 250 videos, the mean attention divergence is 1 βˆ’ rΜ„ = 0.18 Β± 0.03: a systematic reweighting toward faces, gaze, hands, and both agents rather than isolated shifts.

Pretrained attention BGS attention Pretrained+ BGS

The five most-divergent videos. Full figure

Pretrained attention BGS attention Pretrained+ BGS
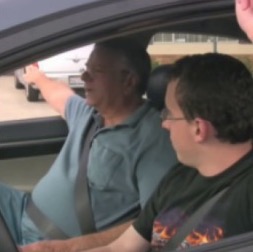
Original frame

One video across its temporal slices: two people in a car. Full figure

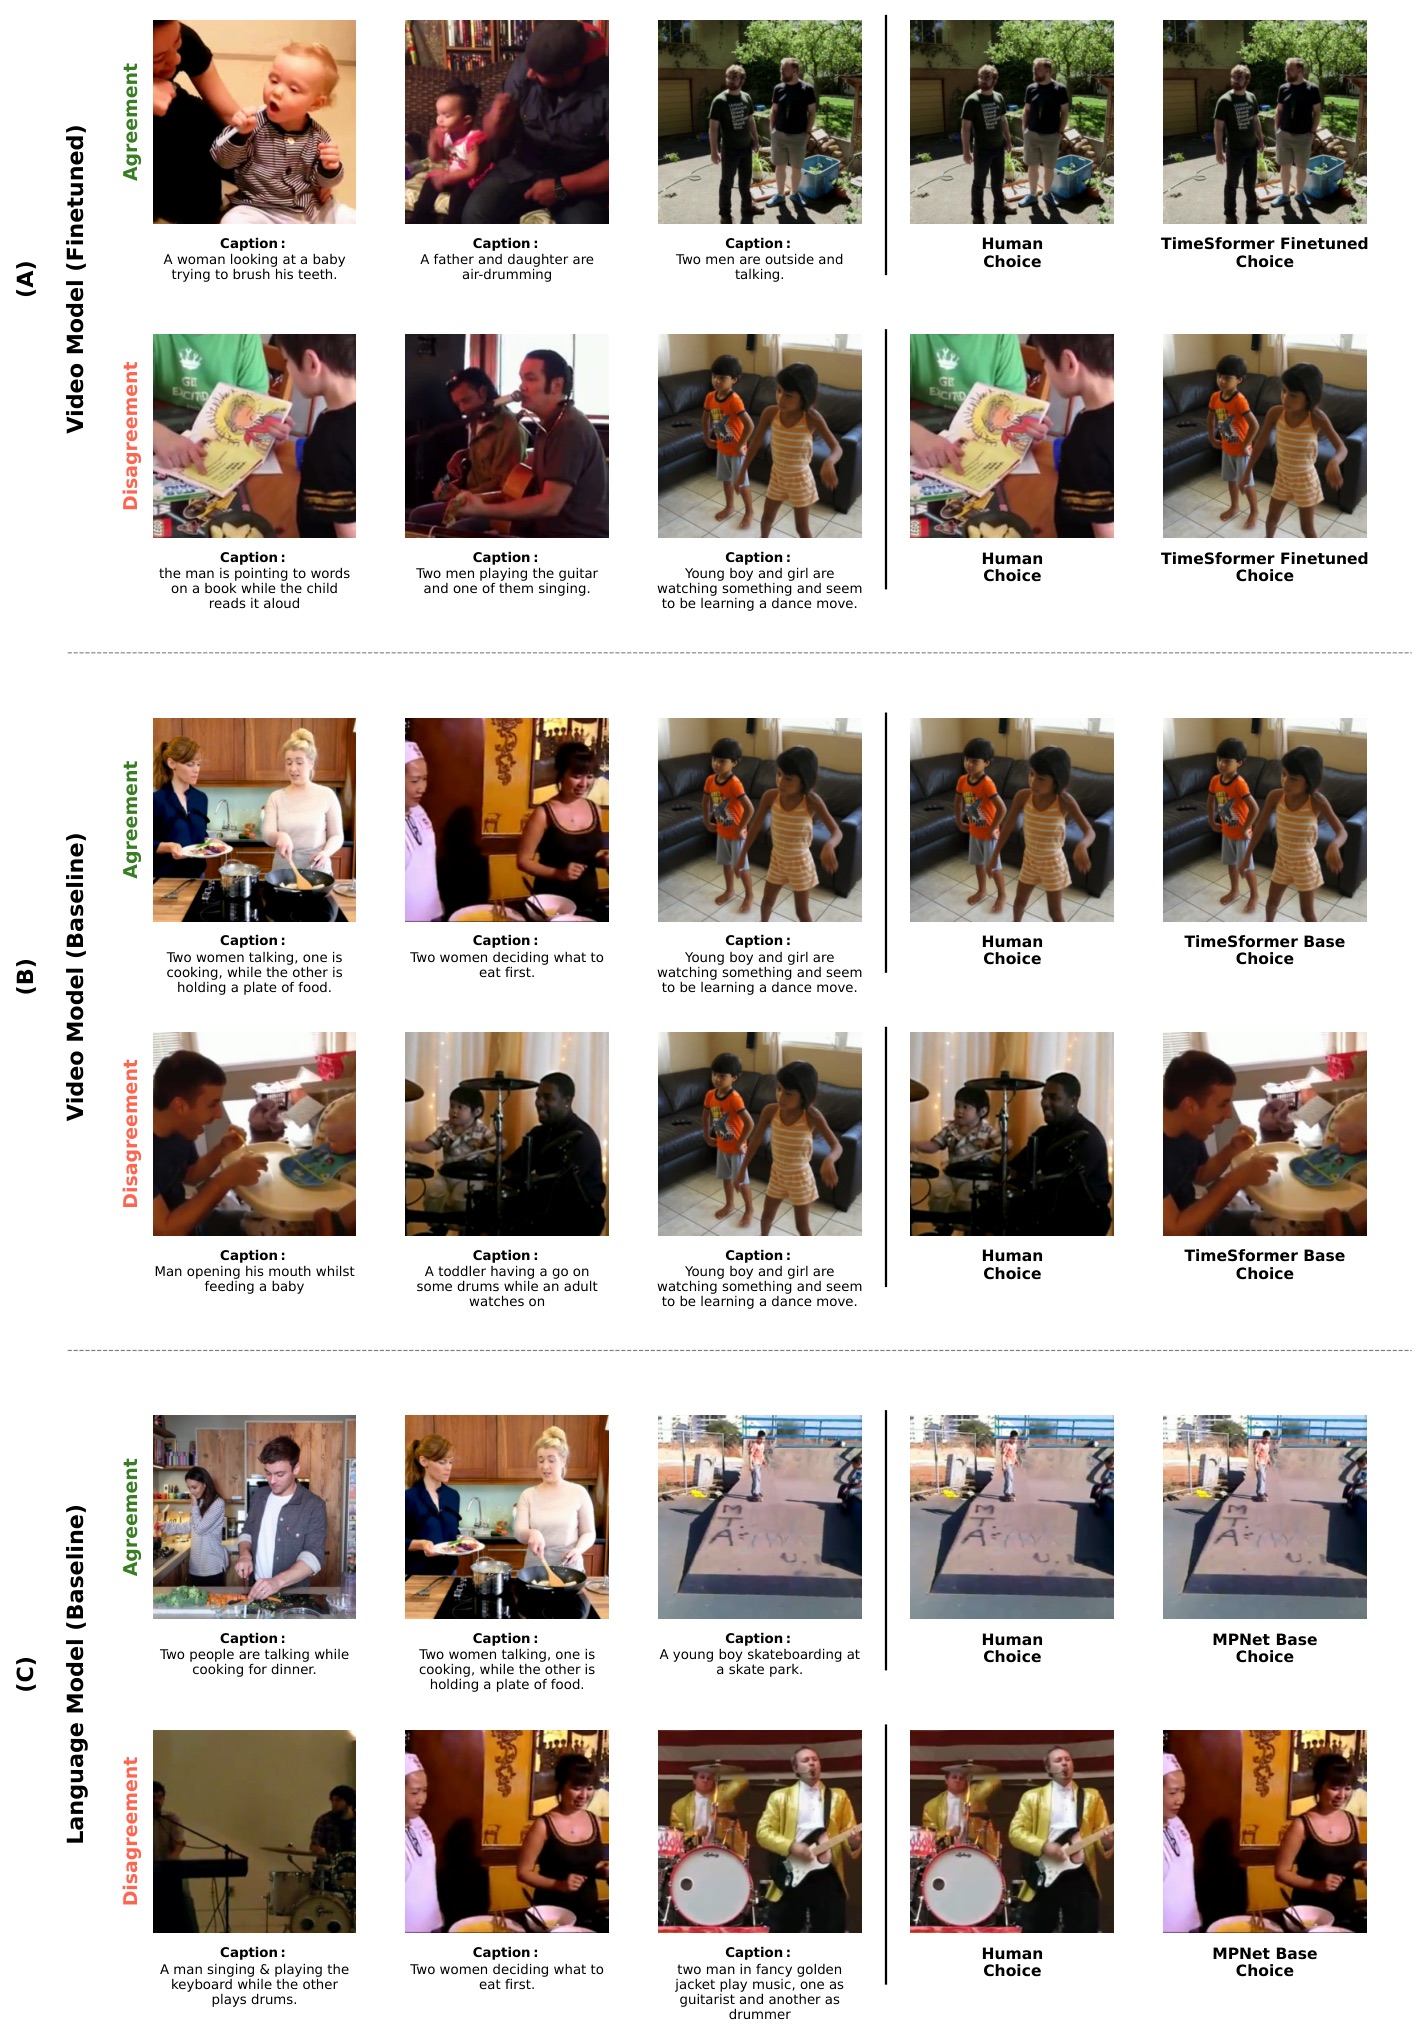
Examples of human-model agreement on odd-one-out triplets
Triplet examples. Cases where the fine-tuned model agrees with the human odd-one-out choice while the pretrained model and MPNet do not.

05What BGS learns generalizes

We froze the BGS-aligned V-JEPA 2.1 ViT-B encoder and tested it on PHASE: two-agent interactions rendered as moving shapes, with no faces, bodies, or scene context. A linear probe on 400 videos, evaluated on the 100-video generalization set, classifies friendly / neutral / adversarial interactions:

3-way social interaction accuracy on PHASE
Bars start at chance (33%)

PHASE stimuli: two triangle agents interacting in a 2D world
PHASE stimuli. Two agents (triangles) move in a 2D physical world with walls, obstacles and goals, in interactions such as collaborate, help, hinder, follow, and chase.

To our knowledge, this is the first demonstration that pixel-level video representations reach prior baselines on this benchmark β€” matching a hand-designed inverse-planning model and human agreement within sampling error.

Ridge-regression probes on five densely annotated attributes show that BGS makes an interpretable social-affective geometry linearly accessible β€” although no attribute labels were ever used in training.

Arousal, dominance, and valence improve substantially over the pretrained baseline.
Intimacy improves modestly; communication declines slightly.
The language-distilled control fails to reproduce the gains on 4 of 5 attributes β€” the exception is communication, where caption words like β€œtalking” carry the answer.

Linear probes on UCF101 (split 1, frozen backbones, 3 seeds) show no catastrophic forgetting:

78.2 β†’ 80.3%
V-JEPA 2.1 top-1 (+2.1 pp)
95.8 β†’ 95.7%
TimeSformer top-1 (unchanged)

07Takeaways

Social perception is latent in video models. Pretrained backbones carry enough information about the social world; a compact behavioral signal makes it usable.
Relational judgments are an efficient supervision signal. Unlike preference learning they shape representations, not outputs; unlike attribute labels they capture the integrated structure of human judgment.
Gains are general. Consistent across four backbones and pretraining objectives, with zero-shot transfer and no loss of action recognition.

08Citation

@inproceedings{garcia2026bgs,
  title     = {Behavioral Geometric Supervision Aligns Video Foundation
               Models with Human Social Perception},
  author    = {Garcia, Kathy and Isik, Leyla},
  booktitle = {Advances in Neural Information Processing Systems (NeurIPS)},
  year      = {2026},
  note      = {Oral},
  url       = {https://arxiv.org/abs/2510.01502}
}